MSME Financial Health Card
An explainable alternative-data credit-decisioning prototype for thin-file MSMEs, keeping score, risk, rules, policy, and provenance inspectably separate.
Synthetic offline evidence covers a 40,000/10,000 train/holdout split, a separately labeled 50,000-row portfolio, and one illustrative thin-file decision.
Alternative evidence for a thin-file decision
New-to-Credit and New-to-Bank MSMEs often lack bureau history, audited financials, or collateral records. This self-directed prototype tests whether consent-oriented operating evidence can support an inspectable pre-screening decision without pretending that absence is repayment performance.
The design constraint is practical: use evidence a small firm can plausibly produce, keep structural missingness explicit, and make each downstream judgment reviewable.
Product surface
Explore nine full-page captures from the running FastAPI application, rendered against its 50,000-record synthetic store.
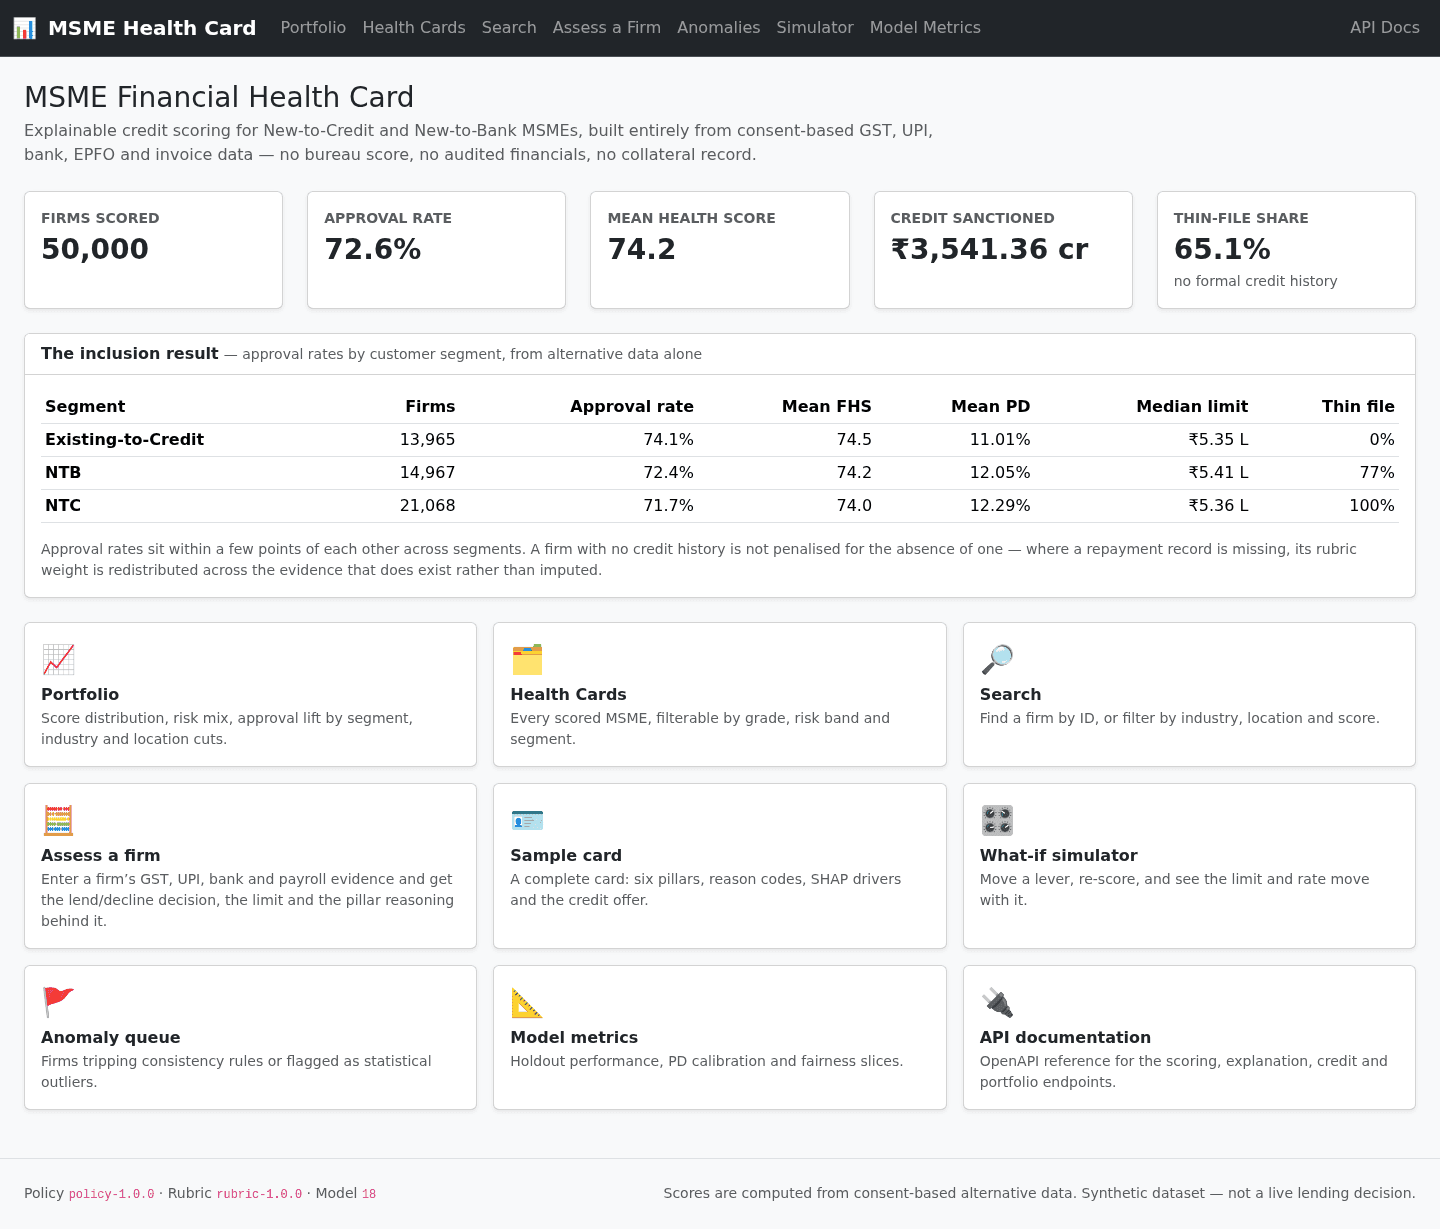
Overview
1 / 9The entry view pairs the 50,000-firm portfolio headline with the inclusion table and direct routes into every review workflow.
Watch the credit decision system work
Scrub the timeline to see a 33-field snapshot become features, six pillar scores, model risk, consistency checks, policy terms, and an explainable card.
Load record
Validate one alternative-data snapshot at the edge
MSME0000042 arrives with GST, UPI, bank, payroll, invoice, and firmographic evidence.
The typed boundary accepts the ID plus 33 allowlisted fields while preserving absent repayment history as absence.
A 33-input contract that does not invent history
The typed contract accepts 33 raw inputs across GST filing and turnover, UPI and banking flows, EPFO and payroll regularity, invoices, and firmographics. Label-block columns stay behind an allowlist, while derived ratios are calculated only after validation.
For the 32,556 synthetic firms without an existing loan, repayment history remains structurally missing. The transparent rubric redistributes unavailable repayment weight across evidence that exists rather than mean-imputing a fictional credit record.
Score, risk, rules, and policy have different owners
Six monotone pillar rubrics own the Financial Health Score. A statistical model separately estimates the generated probability-of-default target and eligibility; eight named consistency rules surface conflicting GST, bank, UPI, payroll, and invoice evidence.
A versioned policy then owns risk band, knock-outs, limit, tenor, and indicative pricing. The separation keeps a reviewer from mistaking a transparent score, a statistical estimate, a deterministic flag, and a policy choice for one opaque verdict.
One illustrative decision remains decomposable
For illustrative synthetic record MSME0000042, six pillar contributions add up to 77.6 points. The separate model estimate is a 6.9% generated probability of default; the policy returns eligible, Medium risk, ₹273,000, 24 months, and 13.5%.
Named rubric reason codes explain the score; SHAP names effects on the estimated generated probability of default; consistency rules report broken invariants; and policy explains the recommendation.
Decision evidence
MSME0000042 decision decomposition
How does one synthetic record move from pillar evidence to an inspectable decision?
Transparent rubric score
77.6 / 100A · StrongGenerated-PD model
6.92%Medium risk · generated targetPolicy recommendation
Eligible · ₹273,00024 months · 13.5% indicativeSix pillar points
Exact sum 77.59696 → displayed 77.6- Compliance23.508694 pts
- Payment behaviour21.093783 pts
- Cash flow16.459572 pts
- Revenue consistency8.179915 pts
- Business stability5.293083 pts
- Business growth3.061912 pts
Named rubric reasons
Arithmetic witness- StrengthTransaction volatility
- StrengthSupplier payment punctuality
- StrengthGST filing timeliness
- ConstraintRevenue growth rate
- ConstraintYears in operation
- ConstraintOverdraft usage
Named SHAP drivers
Model-risk witness- Transaction volatility indexlowered estimated generated PD
- Average invoice payment delaylowered estimated generated PD
- Customer concentration ratioraised estimated generated PD
- GST filing timelinesslowered estimated generated PD
- Vendor payment timelinesslowered estimated generated PD
- Salary consistencylowered estimated generated PD
Named consistency rules
No rule triggered for this record; GST, bank, and UPI evidence agreed.
Read The 6 exact pillar contributions close to 77.59695988864718, while SHAP explains a separate 6.92% generated-PD estimate and policy owns the recommendation.
Interpretation note Pillar points, SHAP effects on PD, and policy outputs are separate evidence layers.
Values and denominators
| Layer | Value | Exact source number |
|---|---|---|
| Compliance | Transparent pillar score | 23.50869448578008 |
| Payment behaviour | Transparent pillar score | 21.093783060735085 |
| Cash flow | Transparent pillar score | 16.459572315694775 |
| Revenue consistency | Transparent pillar score | 8.179915099449705 |
| Business stability | Transparent pillar score | 5.293082768573887 |
| Business growth | Transparent pillar score | 3.0619121584136444 |
| Financial Health Score | Score | 77.59695988864718 |
| Estimated generated PD | Model risk | 0.06915075331926346 |
| Indicative credit limit | Policy decision | 273000 |
| Tenor | Policy decision | 24 |
| Indicative rate | Policy decision | 13.5 |
Holdout gates, calibration, and cohort error stay scoped
The model is evaluated on a fixed 10,000-row synthetic holdout after training on 40,000 separate rows. Eligibility discrimination, generated-PD error, Financial Health Score fit, and every pillar rubric are read against configured gates.
Ten equal-frequency bins compare predictions with the generated PD target—not observed defaults. Customer segment, industry, location, and business type slices retain their row counts, PD MAE, and signed bias so stability can be inspected without claiming fairness certification.
Model evidence
Holdout evaluation
Does the model clear its documented gates across each decision layer?
- ROC-AUC0.98Eligibility
- PR-AUC0.99Eligibility
- Generated PD Adjusted R²0.91Generated PD
- Generated PD MAE0.02Generated PD
- MAE2.18Health score
Read All 9 configured model/rubric gates clear on the fixed holdout; the table retains supporting metrics instead of reducing the evaluation to ROC-AUC.
Values and denominators
| Layer | Metric | Result | Gate | Outcome |
|---|---|---|---|---|
| Eligibility | ROC-AUC | 0.98 | ≥ 0.95 | Pass |
| Eligibility | PR-AUC | 0.99 | — | Supporting metric |
| Eligibility | Precision | 0.95 | — | Supporting metric |
| Eligibility | Recall | 0.95 | — | Supporting metric |
| Eligibility | F1 | 0.95 | — | Supporting metric |
| Generated PD | Adjusted R² | 0.91 | — | Supporting metric |
| Generated PD | MAE | 0.02 | ≤ 0.03 | Pass |
| Health score | Adjusted R² | 0.82 | — | Supporting metric |
| Health score | MAE | 2.18 | ≤ 2.5 | Pass |
| Pillars | Business growth adjusted R² | 0.94 | ≥ 0.75 | Pass |
| Pillars | Business growth MAE | 2.27 | — | Supporting metric |
| Pillars | Business stability adjusted R² | 0.88 | ≥ 0.75 | Pass |
| Pillars | Business stability MAE | 2.2 | — | Supporting metric |
| Pillars | Cash flow adjusted R² | 0.99 | ≥ 0.75 | Pass |
| Pillars | Cash flow MAE | 0.5 | — | Supporting metric |
| Pillars | Compliance adjusted R² | 0.99 | ≥ 0.75 | Pass |
| Pillars | Compliance MAE | 0.37 | — | Supporting metric |
| Pillars | Payment behaviour adjusted R² | 0.94 | ≥ 0.75 | Pass |
| Pillars | Payment behaviour MAE | 1.07 | — | Supporting metric |
| Pillars | Revenue consistency adjusted R² | 0.9 | ≥ 0.75 | Pass |
| Pillars | Revenue consistency MAE | 2.04 | — | Supporting metric |
Generated-PD holdout calibration
How closely does predicted generated PD track its synthetic target?
Read 10 generated-target means stay close to the identity line; this is calibration to a generated target, not observed repayment.
Interpretation note The reference values are mean predictions; fact values are mean generated targets.
Values and denominators
| Bin | Rows | Interval | Mean predicted | Mean generated target |
|---|---|---|---|---|
| 1 | 1,000 | 0.008502–0.036461 | 0.027505 | 0.027796 |
| 2 | 1,000 | 0.036461–0.04966 | 0.04315 | 0.043209 |
| 3 | 1,000 | 0.04966–0.062477 | 0.05607 | 0.055572 |
| 4 | 1,000 | 0.062477–0.076309 | 0.06907 | 0.069704 |
| 5 | 1,000 | 0.076309–0.091196 | 0.083595 | 0.084237 |
| 6 | 1,000 | 0.091196–0.11188 | 0.101246 | 0.101571 |
| 7 | 1,000 | 0.11188–0.136313 | 0.123158 | 0.121893 |
| 8 | 1,000 | 0.136313–0.17183 | 0.153142 | 0.151158 |
| 9 | 1,000 | 0.17183–0.236607 | 0.200059 | 0.201943 |
| 10 | 1,000 | 0.236607–0.72651 | 0.328357 | 0.331887 |
What-if review changes the scenario, not the record
The simulator lets a reviewer adjust explicit, controllable levers—such as GST filing timeliness or overdraft use—then compare score, generated-PD risk, band, limit, and pricing with the baseline.
Only the scenario is re-scored. The stored synthetic MSME record remains unchanged, so sensitivity can be inspected without presenting the simulated recommendation as an offer.
What the prototype proves—and what should be tested next
This self-directed synthetic-data prototype demonstrates a typed alternative-data contract, leakage-aware model evaluation, exact score arithmetic, calibrated generated-target behavior, versioned recommendations, and reviewable failure signals. It does not demonstrate production deployment or real borrower outcomes.
The highest-value next experiment is prospective validation on consented operating data joined to observed repayment performance: freeze the feature, rubric, and policy versions; measure calibration and error by cohort over time; then retrain or reject the generated-PD mapping before any real credit use.